 QwenImage21.net
Qwen Image vs GPT Image: Briefs, Revisions, and Delivery
Compare model access, iterative editing, instruction following, and the work needed to deliver a finished image.
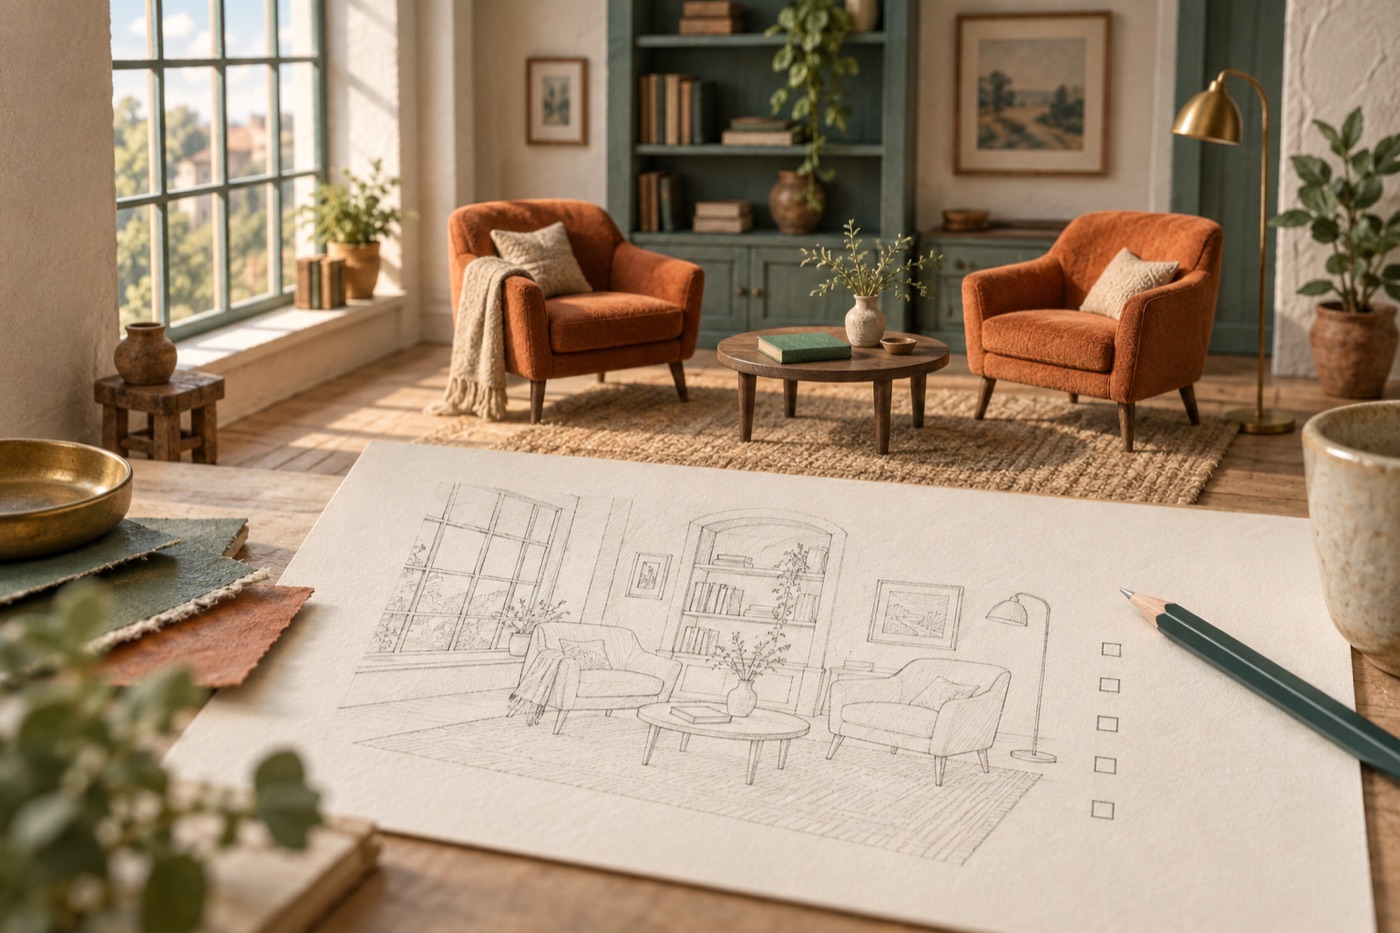
The useful question is not whether Qwen Image or GPT Image can make an attractive picture. It is which workflow gets your particular brief to an approved asset with fewer corrections. This guide compares approaches using documented capabilities; it does not report original benchmark results.
Distinguish the model from the interface
OpenAI documents image generation and editing through its API. Qwen publishes model checkpoints, including Qwen-Image-2512. A conversational application, an API integration, and a hosted image website can wrap those capabilities very differently. Verify the actual model ID and available input controls before testing. References: OpenAI image guide and Qwen-Image-2512.
If access to model weights matters to your deployment, investigate the specific Qwen checkpoint and its requirements. If your priority is a managed integration, compare the actual endpoints you can purchase and operate. Neither choice removes the need to review output quality.
Test an instruction-heavy brief
Use this original task:
Create a landscape editorial illustration of a small reading room. Exactly two armchairs face one low table. One green book rests on the table. A tall window is on the left. Leave the upper-right area clear for an added title. Warm evening light, no visible text.
Before generating, turn the brief into a checklist: two chairs, one table, one book, left window, clear title area. Score those requirements separately from visual appeal. This prevents an attractive but inaccurate image from winning on first impression.
Test the second request too
On editing-capable workflows, ask to change the chairs to blue while preserving everything else. Compare what changed beyond the chair color. Then request a different crop and check whether important objects remain intact. Use the same source image and equivalent edit instructions wherever possible.
A model that produces a strong first draft may still require substantial cleanup after revisions. Track the whole sequence, including rejected outputs and time spent rewriting instructions.
Make the decision at delivery
Inspect the final dimensions, text accuracy, object consistency, and export options required by your project. Calculate cost per accepted asset, including retries and manual cleanup. Use a small collection of your own briefs to decide; a single memorable sample does not establish a general ranking.
Prepare equivalent briefs using our prompt guide, then record attempts with the model-evaluation workflow. You can try your initial text brief in the image generator.
Cover: editorial illustration generated with Codex, not an output from the models compared or a benchmark sample.